DQN, DDPG, SAC, and Modern RL Applications
From DQN to continuous action spaces: the deterministic policy gradient, TD3's 3 fixes, SAC's maximum-entropy formulation, the squashed Gaussian policy, and where these ideas stand in modern robot learning.
Notation. Critic params , actor params , target networks . Note this is the opposite of the lecture notes convention, where is the actor and the critic — the DQN/DDPG/TD3/SAC papers all use the convention below, so it's easier to read the code against it.
# Background: Q-learning & DQN
What does mean? For a fixed policy , is the expected discounted return if we start in state , take action first, and follow from the next step onward:
Here is the reward after taking , and for ; the expectation includes both policy randomness and environment transitions . The superscript labels which policy we follow afterward, not a power. The first action need not be the one would choose.
vs. . Plain is a generic action-value function; in the update rules below it denotes the current learned estimate. Evaluating a fixed aims for , while Q-learning aims for , the optimal action-value function. The current estimate need not equal either one yet.
Goal: learn the optimal action-value function , the expected discounted return starting from , taking , then acting optimally.
Bellman optimality equation:
# Tabular Q-learning update: evaluation & improvement
Given a transition and reward , separate the update into 2 ideas (assume is nonterminal for now).
1. Policy evaluation — how good is the current policy? Hold a policy fixed and use its action probabilities at the next state to form a TD target:
This changes the value estimate, not the policy. Repeated evaluation of a fixed aims to recover ; one TD update is only a partial evaluation step.
2. Policy improvement — which action should we choose? Hold the current Q-table fixed and define a greedy policy (break ties arbitrarily):
Why instead of ? Here means the set of all maximizing actions, while is one chosen action from that set. For example, if left and right both have Q-value and stay has Q-value , then ; choosing satisfies the relation. Writing is common shorthand when is understood to return a single action using a tie-breaking rule.
We write this greedy policy as a deterministic action map . In the evaluation formula above, instead denotes an action probability; a deterministic policy assigns probability to its chosen action and to the others.
This changes the policy, not the value estimate. With an exact , the policy improvement theorem guarantees that this greedy policy is at least as good as .
Putting them together gives Q-learning. At each update, use the greedy policy implied by the current table as the target policy. Its evaluation target becomes
so the combined update is
The supplies the greedy improvement, and moving toward the resulting target supplies a TD evaluation step. Q-learning interleaves these through Bellman optimality backups; it does not evaluate each fixed policy to convergence before improving it. It is also off-policy: the behavior policy that collected the transition can be exploratory (e.g., -greedy), while the target policy is greedy.
DDPG makes these roles explicit in separate networks: the critic evaluates the actor's policy, and the actor improves its actions using the critic.
# From a Q-table to a Q-network
When state spaces are large (e.g., images), we can't store a table, so approximate w/ a NN and regress on the squared TD error:
Naive deep Q-learning is unstable, from 2 sources:
- correlated samples: sequential transitions are highly correlated
- moving target: the target shifts as we update
DQN (Mnih et al., 2015) fixes these w/ 2 tricks.
# Trick 1: experience replay
Store transitions in a replay buffer (fixed size, FIFO) and sample random mini-batches for each gradient step.
+: breaks correlation btw consecutive samples
+: reuses data efficiently (each transition used multiple times)
+: reduces non-stationarity of the training data
# Trick 2: target networks
Use a separate target network that updates slowly, so the regression label stops moving under us:
2 ways to update the target network:
| method | update rule | typical value |
|---|---|---|
| hard update | every steps | |
| soft update (Polyak) | each step |
The soft update is what DDPG/TD3/SAC all use: instead of a discontinuous jump every steps, the target drifts smoothly toward the online net. This matters more in the continuous-action setting, where the actor is chasing the critic's gradient and a sudden target jump can knock the policy off a good region.
# Overestimation bias & double Q-learning
The operator makes Q-learning overestimate Q-values. Formally, and don't commute:
Using the same network to both select and evaluate the best action amplifies noise: whichever action happens to have a positive error gets picked, so the target inherits that error. Worse, the inflated target becomes the next regression label, so the bias compounds through bootstrapping.
Double DQN (van Hasselt et al., 2016) decouples the two: the online network selects, the target network evaluates.
# Exploration: -greedy
Common schedule: decay from to over the first env steps.
# Full DQN algorithm
- init replay buffer , Q-network , target network
- for each step:
- select action using -greedy w.r.t.
- execute , observe ; store in
- sample mini-batch from
- compute target
- update by minimizing
- update target network (hard or soft)
# Implementation tip: terminal states
Store a done flag w/ each transition, if is terminal, else :
The term makes sure we don't bootstrap from terminal states, where there is no future return. Every target below carries this factor.
# DDPG (Deep Deterministic Policy Gradient)
DDPG adapts DQN's success (experience replay, target networks) into continuous action spaces using deterministic policies.
# Core theory: the DPG theorem
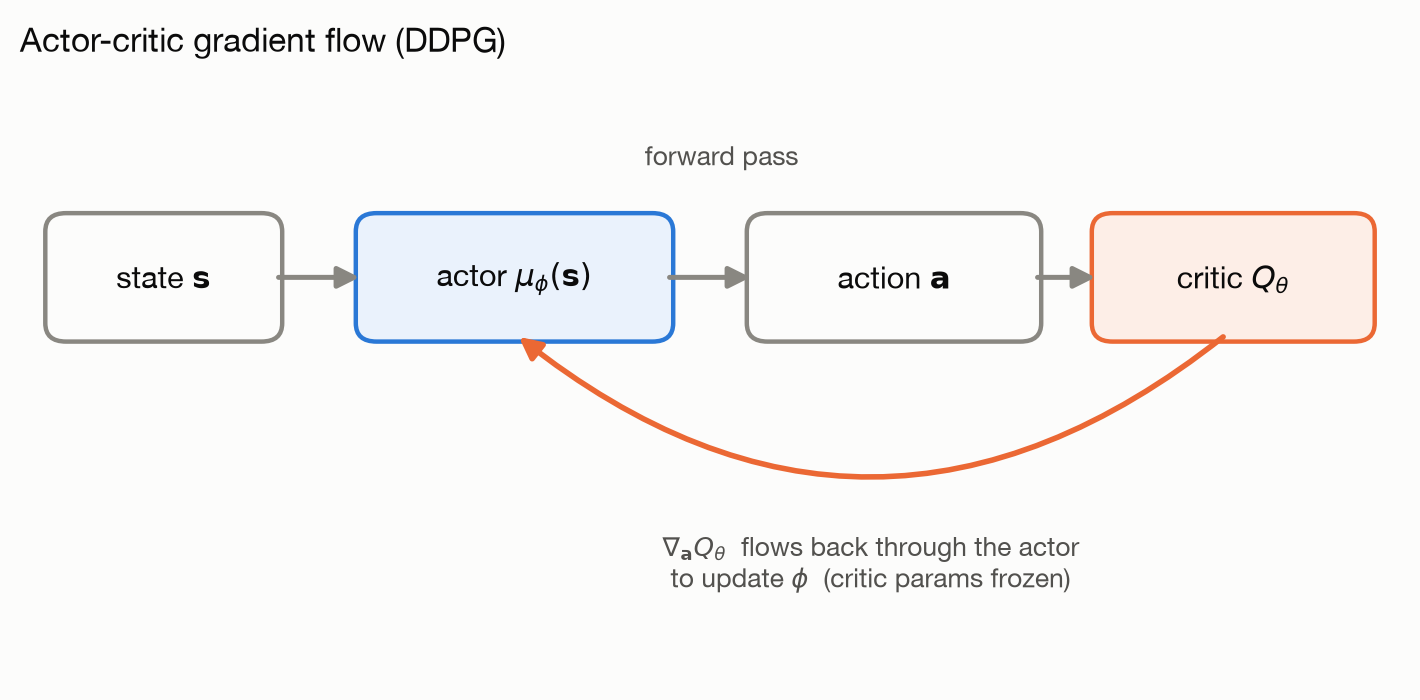
In discrete action spaces is an enumeration; in continuous spaces it is its own optimization problem at every step. Instead, train a deterministic actor to output a high-value action, and let the critic tell it which way to move. The actor learns an approximate maximizer; it does not compute an exact .
For a fixed state, the differentiable path is . Holding the critic parameters fixed, the chain rule gives
- — the critic's gradient w.r.t. the action. At the actor's current action, it points in the direction of the steepest local increase in the estimated Q-value: the coach says how to adjust the wrist (手腕怎么压).
- — the actor's Jacobian w.r.t. its parameters. It describes how changing each network parameter changes the output action: how the muscles control the wrist (怎么调整肌肉). For vector actions this is a matrix, so the transpose maps the critic's action-space gradient back into parameter space.
Multiplying the 2 gives the actor a parameter update direction. In the scalar case this is simply : “教练指出动作往哪改,Actor 再把这个方向传回自己的参数。” Gradient ascent moves along this direction; minimizing the negative Q-value below implements the same update.
What the DPG theorem adds. The chain rule above only differentiates a fixed-state critic output. The deterministic policy gradient theorem (Silver et al., 2014) connects it to the expected long-term return: with the true critic , the appropriate discounted state-visitation weights under , and standard differentiability assumptions, integrating this local gradient gives the policy's return gradient. We do not need to differentiate the environment dynamics or explicitly differentiate the state-visitation distribution. Determinism gives one action per state and a direct gradient path; differentiability is also required.
DDPG's practical approximation. Replace the true critic by and sample states from the replay buffer. With and the replay sampling distribution fixed during the actor step, optimize the surrogate :
This is the exact gradient of the replay surrogate, but generally an approximation to the true return gradient because the critic is learned and replay states come from past behavior policies. In code, freeze the critic's parameters during the actor update, while keeping the gradient through its action input; detaching the action or critic output would break the chain.
# Critic loss (evaluation)
MSE against the target network:
# Actor loss (improvement)
Maximize the critic's Q-value estimation, minimized via the negative sign:
# Target networks: soft update
Both the critic and the actor keep a target copy, updated by Polyak averaging every step rather than hard-copied every :
w/ . This is the single change that makes deep Q-learning workable in continuous spaces — without it the actor and critic chase each other and diverge.
# Flaws
-: suffers from severe overestimation bias in Q-values
-: exploration is rigid, relying on hard-coded additive noise (e.g., Gaussian or Ornstein-Uhlenbeck) whose scale is a hyperparameter you must tune per env
# TD3: 3 fixes for DDPG
TD3 (Fujimoto et al., 2018) keeps DDPG's structure and patches its failure modes. SAC borrows the first fix; the other 2 are worth knowing b/c they explain why the first one is needed.
1. Clipped double Q-learning. Keep 2 independent critics and take the min for the target:
Double DQN's select/evaluate split is not enough here: in actor-critic the actor is trained through the critic, so the online and target nets stay highly correlated and the decoupling breaks down. Taking the min of 2 critics instead induces a deliberate underestimate. See why underestimation is the safer error below.
2. Target policy smoothing. Add clipped noise to the target action, so the critic can't exploit a sharp spurious peak:
This is a regularizer that enforces the prior that similar actions should have similar values.
3. Delayed policy updates. Update the actor (and the target nets) once every critic updates, typically . A policy trained against a high-variance critic amplifies the critic's error; letting the critic settle first reduces that.
# SAC (Soft Actor-Critic)
SAC is built on maximum-entropy RL, optimizing for both maximum reward and maximum policy randomness to ensure robust exploration and prevent local optima.
# From Q-learning to actor-critic
Problem w/ continuous actions: can't compute exactly.
Solution: learn a policy (actor) alongside the Q-function (critic).
- critic : estimates expected return
- actor : outputs actions, replacing the
# The maximum-entropy objective
SAC adds an entropy bonus to the usual RL objective:
where is the conditional entropy.
Why entropy regularization?
+: encourages exploration — the policy doesn't collapse to deterministic too early
+: more robust, b/c it captures multiple good solutions instead of committing to one
+: better convergence in practice
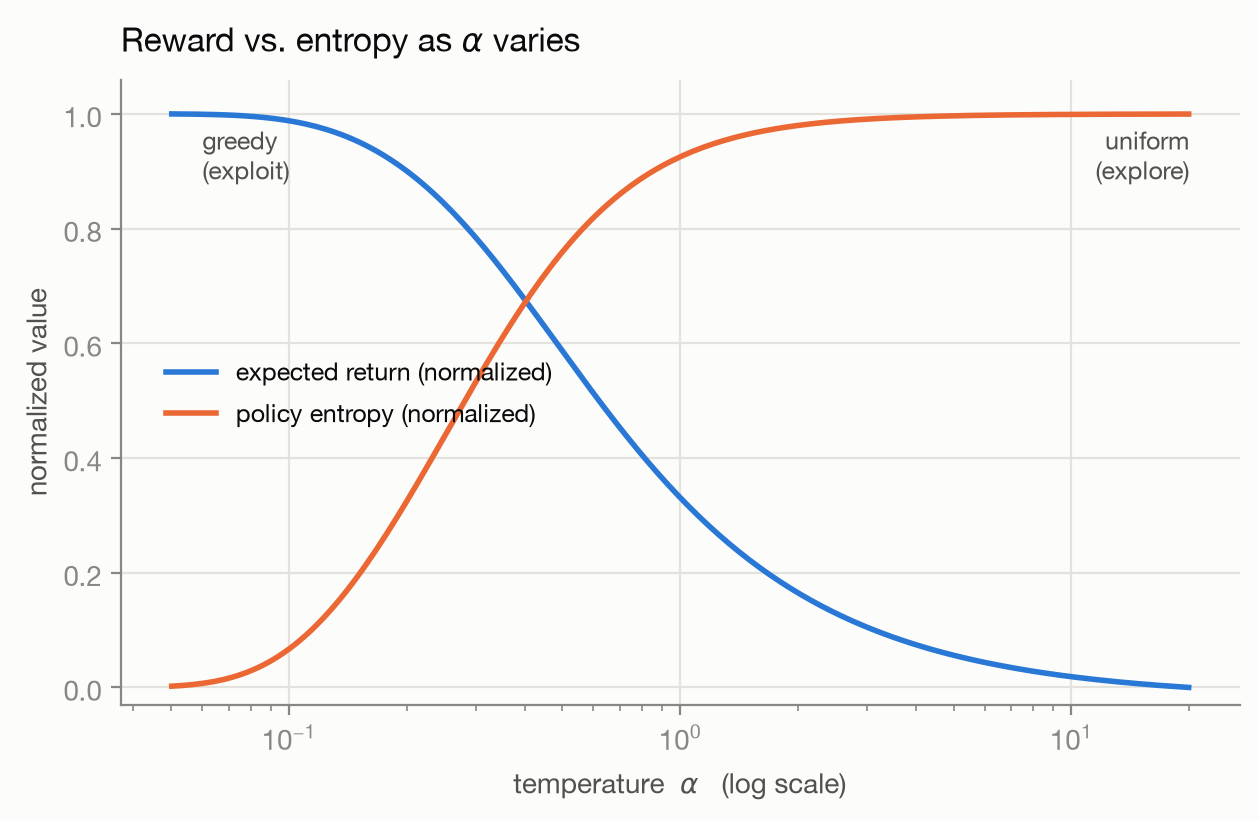
The temperature controls the exploration vs. exploitation tradeoff. Note the contrast w/ DDPG: exploration is now part of the objective rather than noise bolted on at action-selection time.
# Soft policy iteration: the 2 theoretical pillars
The whole algorithm is a practical approximation of soft policy iteration, which alternates 2 steps, each w/ its own guarantee.
Lemma 1 (soft policy evaluation). First fold the entropy bonus into the state value:
Then the soft Bellman backup operator is
Substituting gives the form the critic actually regresses on:
The lemma: repeatedly applying to any bounded initial converges to the true soft Q-value . The proof is the standard one — is still a -contraction, w/ the entropy term riding along as part of an augmented reward . Compare this against the SAC critic target below: they are the same expression, w/ and the as the practical approximations.
Lemma 2 (soft policy improvement). Improve the policy by maximizing soft value — expected Q plus entropy — at each state:
This is the natural improvement step, and negating it is exactly the actor loss you implement below. Two facts make it concrete:
- Unconstrained, the maximizer is the Boltzmann distr — an action's prob grows exponentially in its Q-value, w/ as temperature ( recovers the greedy , gives uniform). Derived in the appendix.
- The paper writes this as a KL projection onto that same Boltzmann distr:
The two forms are the same optimization (derived just below). The restriction is what turns "solve exactly" into "project": unconstrained we'd land on the Boltzmann distr, but confined to a tractable family we settle for its closest member.
The lemma: for all — monotone improvement.
Theorem (soft policy iteration). Alternating the 2 converges to the optimal maximum-entropy policy in . SAC is the function-approximation version: rather than running each step to convergence, it takes a single gradient step on each per env step.
# The mathematical bridge: the KL form is the same optimization
Lemma 2's two forms — the argmax of and the KL projection — are one problem written twice. Rewrite the entropy as , flip the sign to a minimization, then divide by (neither move shifts the argmin):
The Boltzmann target isn't pulled from nowhere — it's the exact unconstrained optimum from the appendix. By its definition , so substituting:
is constant in , so it drops — leaving Lemma 2's projection exactly.
The useful direction is the reverse one. What you actually implement is the plain (the braced term above); the KL reading is what certifies it's a principled projection onto the Boltzmann distr rather than an arbitrary penalty.
# What SAC changes relative to DDPG
If you have to name it in one breath: SAC changes the actor and the critic, one thing each.
- The actor becomes stochastic — a reparameterized squashed Gaussian instead of DDPG's deterministic , w/ an entropy term carried into both the target and the actor loss. Exploration moves into the objective; DDPG's hand-tuned additive noise is gone.
- The critic becomes 2 critics w/ a — clipped double-Q borrowed from TD3, to cancel DDPG's overestimation bias.
Everything else DDPG already had: replay buffer, Polyak-averaged target networks, and an actor trained by backprop through the critic.
Those 2 changes map exactly onto DDPG's 2 flaws — rigid exploration and overestimation. The comparison table breaks all of this down line by line.
The rest of this section works through the machinery each change needs: the reparameterization trick and the squashed Gaussian for change 1, clipped double-Q for change 2, and auto-tuning as a convenience on top of change 1 rather than a change of its own.
# Stochastic policy w/ reparameterization
The reparameterization trick bypasses the inability to backprop through random sampling. The network outputs deterministic and , and the randomness comes from external standard noise:
The squashes actions to ; the reparameterization allows backprop through sampling, since carries no parameters and the path is fully differentiable.
In code the whole trick is one method call — rsample() instead of sample(), which keeps the path in the autograd graph so can flow back to :
dist = actor(s)              # a squashed-Gaussian distribution over actions
a = dist.rsample()           # sample()  → detaches a from φ (score-function estimator only)
                             # rsample() → keeps ∂a/∂φ (the low-variance pathwise gradient)
logp = dist.log_prob(a)      # closed-form, including the tanh Jacobian correction below
2
3
4
# Is the Gaussian specific to SAC, or just a convenient choice?
Just a convenient choice. Nothing in Lemma 1 or Lemma 2 assumes a Gaussian — the ideal target is always the Boltzmann distr , which is generally not Gaussian. Lemma 2 says the policy improves when we project onto the target within our chosen policy class , and the squashed Gaussian is simply a tractable .
What SAC actually requires of the policy class is 3 things:
- reparameterizable, so the actor loss has a low-variance pathwise gradient
- a closed-form , b/c appears in all three losses
- bounded support matching the action space
The Gaussian happens to satisfy all 3 cheaply. Other valid choices: a Categorical distr for discrete SAC (there you can drop reparameterization entirely and sum the entropy over actions exactly), or a mixture of Gaussians / normalizing flow when the action distr is genuinely multi-modal. What breaks the recipe is a policy w/ no tractable density — which is exactly the problem diffusion policies run into.
# Clipped double-Q (from TD3)
To reduce overestimation, SAC uses 2 Q-networks and takes the minimum. Combined w/ the entropy term, the target is:
Note is a fresh sample from the current policy, not the action stored in the replay buffer — this is the standard off-policy correction.
# Why does taking the min suppress overestimation?
Because the 2 error directions are not symmetric in their consequences.
Write each critic as truth plus noise, . The in the target systematically selects whichever action drew a positive , so and the target is biased upward. Taking over 2 critics pulls in the opposite direction — — so the 2 biases partly cancel.
The deeper reason to prefer erring low is that the 2 kinds of error have very different dynamics under bootstrapping:
- an overestimate is self-reinforcing: an action that looks spuriously good gets selected by the /actor, its inflated value becomes the next regression target, and the error propagates backward through the whole value function
- an underestimate is self-correcting: an action that looks spuriously bad simply stops being taken, so the wrong value never gets amplified into other targets
So a deliberate pessimistic bias is cheap insurance. The cost is real but bounded — the agent can be slow to discover genuinely good actions it currently underrates.
# Automatic temperature tuning
Instead of manually setting , learn it by minimizing
where is the target entropy, typically .
The gradient is , so if the current entropy , increases to force exploration, and vice versa. It's a feedback controller holding entropy at a setpoint.
Implementation tip: optimize instead of directly to guarantee .
# SAC loss functions
Critic loss, for each (the squared TD error):
Actor loss (the braced term from the bridge — Lemma 2's improvement step, negated):
Temperature loss: exactly from automatic temperature tuning above.
Note the two roles of : the critic loss regresses on the buffer action, while the actor and temperature losses use a fresh reparameterized sample . The critic's TD target carries a third, separate sample (the clipped double-Q target).
In PyTorch the three losses map almost line-for-line onto the equations above:
# --- critic: regress both Q_i onto the shared soft TD target ---
with torch.no_grad():                                   # no gradient through the target
    next_dist = actor(next_s)
    next_a = next_dist.sample()                         # sample ok here: we're in no_grad
    next_logp = next_dist.log_prob(next_a)
    next_q = torch.min(target_q1(next_s, next_a),
                       target_q2(next_s, next_a))        # clipped double-Q
    y = r + gamma * (1 - d) * (next_q - alpha * next_logp)   # soft TD target: − α log π
loss_q = F.mse_loss(q1(s, a), y) + F.mse_loss(q2(s, a), y)

# --- actor: minimize  E[α log π − Q]  on a fresh reparameterized sample ---
dist = actor(s)
a_new = dist.rsample()                                  # rsample: keep ∂a/∂φ for the pathwise grad
logp = dist.log_prob(a_new)
q_new = torch.min(q1(s, a_new), q2(s, a_new))
loss_pi = (alpha * logp - q_new).mean()

# --- temperature: drive entropy toward the setpoint H̄ ---
loss_alpha = -(log_alpha.exp() * (logp + target_entropy).detach()).mean()
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
Three details carry all the math: rsample() (not sample()) makes the actor loss a low-variance pathwise gradient; the buffer action a feeds the critic while the fresh a_new feeds the actor; and the target uses frozen target_q* under no_grad, but the actor keeps the gradient through q1/q2's action input (detaching it would break the DPG-style chain).
# DDPG vs. TD3 vs. SAC
| DDPG | TD3 | SAC | |
|---|---|---|---|
| policy | deterministic | deterministic | stochastic |
| # critics | 1 | 2, take | 2, take |
| exploration | additive noise at act time | additive noise at act time | entropy term in the objective |
| target action | |||
| entropy term | none | none | in target & actor loss |
| actor update | every step | every critic steps | every step |
| target update | Polyak, | Polyak, | Polyak, |
| key hyperparameter | noise scale | noise scale, | (and auto-tuned) |
# The squashed Gaussian policy & math corrections
The problem: standard Gaussian distrs have infinite bounds . If an environment clips an out-of-bound action (e.g., clipped to ), the critic evaluates an action that never actually occurred, ruining the Q-value.
The fix: SAC passes the sampled action through a to strictly bound it to :
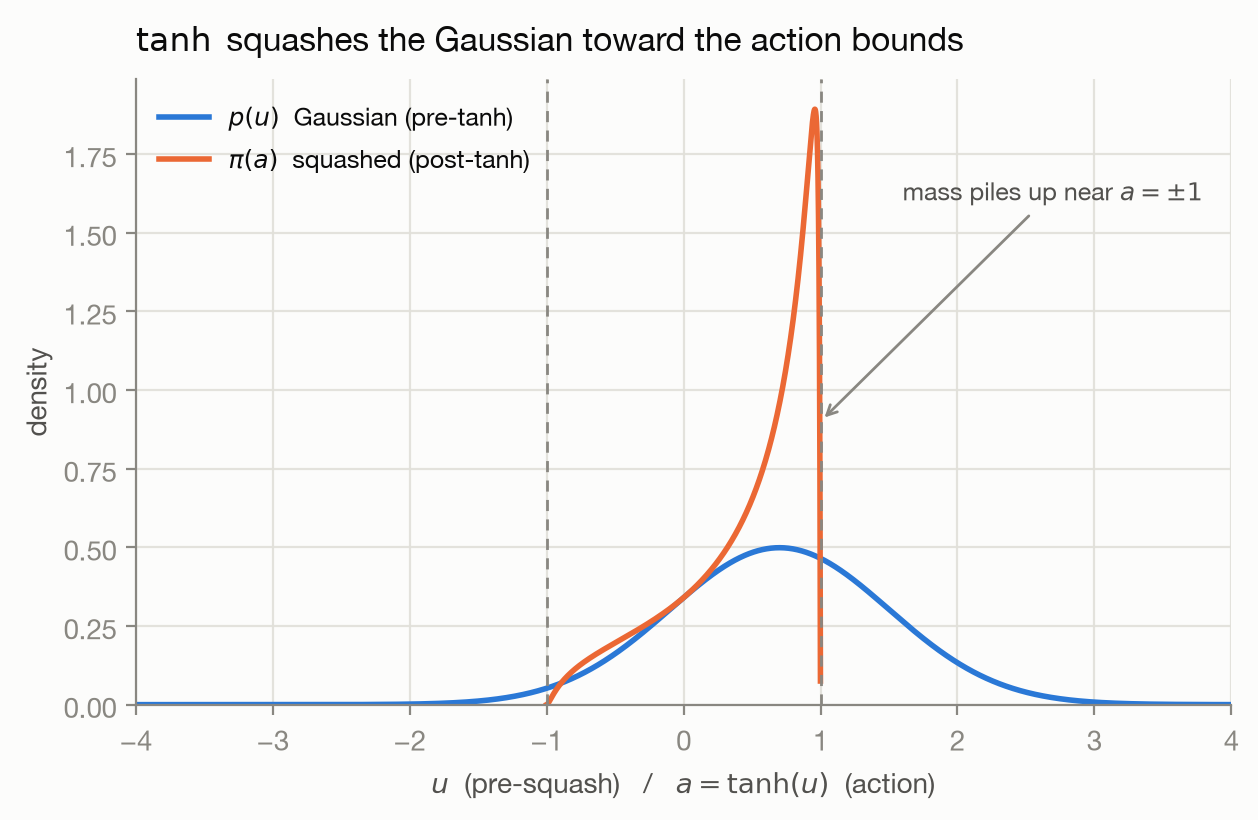
The derivation of the Jacobian correction: b/c squashes the prob density, we must use the change of variables formula to correct the entropy calculation:
The derivative of w.r.t. is exactly . Plugging this in yields the SAC correction term:
# Implementation pitfalls
NaN / gradient explosion. If is large, , making effectively . Computing gives -inf or NaN.
A common patch is to add a tiny epsilon, w/ . But this is only a band-aid, and it biases the log-prob. There is an exact numerically stable form — from :
softplus is stable for both signs of its argument, so this needs no epsilon and introduces no bias. Prefer it.
Clamp . The actor outputs , not ; clamp it to roughly . Unbounded is the other main upstream source of NaN: too large blows up the sample (feeding straight into the pitfall above), too small makes diverge.
Optimize . Same reasoning as : parameterize the temperature in log space so holds by construction.
Rescale to the real action bounds. gives ; for an env w/ bounds , apply , where (action_scale) and (action_bias). The Jacobian term then picks up a constant per dim, which doesn't affect gradients but does shift the reported entropy — so make sure is set in the same units.
Deterministic evaluation. At test time use rather than sampling. The entropy bonus is a training-time exploration device, not part of the behavior you want to deploy.
# Modern applications: is squashed Gaussian still used?
Standard continuous control: yes. For traditional physics simulations (e.g., Mujoco, robotic arms, quadrupeds), the squashed Gaussian policy remains the standard default baseline, and SAC is still the reference off-policy algorithm.
VLA (Vision-Language-Action) models: mostly no — but the reason is not simply "VLAs are discrete". What actually happens is that the unimodal Gaussian head gets replaced, and there are 2 distinct families of replacement:
- action tokenization (discrete): VLAs built directly on an LLM backbone, e.g. RT-2 and OpenVLA, discretize each continuous action dim into bins (typically 256 tokens per dim, covering end-effector delta pose gripper) and emit them as ordinary tokens w/ a categorical distr. This inherits the LLM's next-token machinery unchanged.
- continuous generative heads: the trend in recent robot policies goes the other way — back to continuous actions, but w/ an expressive generative model instead of a Gaussian. Diffusion policies frame action generation as a denoising process, and the -style flow matching action experts attach a continuous action head to a VLM backbone. Neither one tokenizes.
The common thread is multi-modality: a squashed Gaussian can only express one mode per state, so it averages over distinct valid behaviors (go left vs. go right around an obstacle) into a bad middle action. Discretization and diffusion/flow are 2 different ways to buy multi-modality back.
The tradeoff is the one flagged in is the Gaussian specific to SAC: both replacements give up a cheap closed-form — categorical keeps it but only over a discretized space, while diffusion/flow have no tractable density at all. That is exactly why RL post-training on top of these policies is harder than plugging in SAC, and why methods in this space lean on value-weighted or advantage-conditioned supervised objectives rather than an entropy-regularized actor loss.
# Appendix: why the unconstrained optimum is the Boltzmann distribution
Lemma 2 and the KL bridge both lean on one fact: over all distributions, the soft-improvement objective is maximized by . The body asserts it; here is the derivation. It also removes the "rabbit out of a hat" feel of the bridge, where that target is otherwise introduced by definition.
Fix a state and optimize over the density directly. The soft-improvement objective is , i.e.
Form the Lagrangian with a multiplier for normalization, and set the functional derivative w.r.t. to zero (treat each as its own variable):
The comes from . Solving for :
Normalization fixes the leftover constant, giving
This is a maximum, not a saddle: is concave in , so the stationary point is the global max. Positivity holds automatically since , so normalization is the only binding constraint.
One-line corollary of the bridge. Once you have the bridge's identity — objective with the Boltzmann distr — the same result is immediate: with equality iff , so the unconstrained minimizer is . The Lagrangian above is the "from scratch" version that produces the Boltzmann form instead of guessing it; the KL corollary verifies it once the form is known.
Restricting to a tractable family (squashed Gaussians) is what turns this exact solution into Lemma 2's projection: we can no longer land on exactly, so we settle for its closest member in .